What Changed and Why It Matters
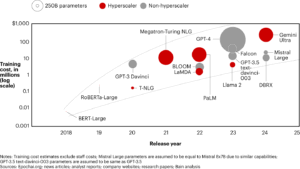
Inference is now the main event in AI. Training grabs headlines; inference writes the bill. The market is quietly moving from GPU-max to GPU-lite — doing more inference with cheaper hardware, tighter runtimes, and workload-aware design.
The signal is broad and consistent. Startups and rivals are shipping inference-first silicon. Researchers show consumer GPUs can rival datacenter parts for latency-tolerant tasks at a fraction of the cost. Builders are rethinking runtimes, not just models. And chipmakers are racing to claim the cost-per-token crown.
“Consumer GPUs can deliver near-H100 AI performance at far lower cost for latency-tolerant workloads.”
Zoom out and the pattern becomes obvious: the unit economics of AI will be set by inference. Founders who design for GPU-lite — fewer, cheaper, or alternative accelerators plus smarter software — will expand margins, reduce power needs, and ship more resilient products.
The Actual Move
Across the ecosystem, the focus is shifting from training horsepower to inference efficiency.
- Rival chip efforts target inference economics. Fast Company reports a wave of competitors pitching inference-optimized chips as Nvidia prioritizes training demand.
- Cerebras introduced an inference offering claiming major speed and price advantages versus Nvidia GPUs, positioning wafer-scale silicon as a low-cost, high-throughput alternative.
- A peer-reviewed study (DCNN Magazine) finds consumer GPUs can approach top-tier GPU performance for certain inference profiles when latency tolerance exists — a cost unlock for many back-end workloads.
- Practitioners are pushing ASIC logic for fixed, high-volume tasks.
“For a pure, high-volume inference task, a GPU is often over-engineered and less cost-effective than an ASIC.”
- Runtime is becoming the battleground. A LinkedIn post from InferX argues the future of GPU inference is runtime, not layers — echoing the industry shift to compilation, scheduling, and memory-aware execution.
- Commentary from the All-In Podcast highlights Nvidia’s balancing act between training and inference, while independent analysis predicts inference costs will fall fast due to cheaper hardware, better models, and a coming supply glut.
- Educators like Chris Fregly are urging engineers to understand GPU internals to unlock real-world speed and cost gains.
“The future of GPU inference isn’t layers, it’s runtime.”
“Hardware gets, like, really cheap.”
The Why Behind the Move
Founders aren’t just cost-cutting. They’re optimizing for control, predictability, and throughput at scale.
• Model
Smaller, distilled, and quantized models shrink memory needs and boost throughput. Many user queries don’t require frontier models. Latency-tolerant tasks open the door to GPU-lite hardware.
• Traction
User growth turns inference into the dominant cost center. Every percent of throughput-per-dollar compounds into more features, trials, and markets.
• Valuation / Funding
Investors now scrutinize gross margins. A GPU-lite stack (consumer GPUs, inference-optimized chips, or selective ASICs) can meaningfully improve margin profiles and runway.
• Distribution
Cheaper tokens enable broader SKUs: free tiers, API credits, and on-device/offline options. Lower unit cost becomes distribution.
• Partnerships & Ecosystem Fit
Clouds push inference services and toolchains; chip startups seek design wins; integrators tune runtimes. The winners plug into existing frameworks with minimal migration pain.
• Timing
Training demand is peaking; supply chains are tight; power caps are real. Meanwhile, open models and quantization tricks mature. The window to lock in cost advantage is now.
• Competitive Dynamics
Nvidia dominates training and strongholds in inference software. Rivals attack the gap: cost-per-token and cost-per-watt. Cerebras, ASIC plays, and consumer GPU clusters present credible alternatives for specific workloads.
“Inference is a global challenge… it’s the one part of AI that everyone will interact with.”
• Strategic Risks
- Over-indexing on niche hardware can create lock-in or tooling debt.
- Latency-tolerant assumptions can break under new UX demands.
- Vendor claims (speedups, 1/5th price) require proof at your workload scale.
- Talent and ops: running GPU-lite reliably still needs deep systems skills.
What Builders Should Notice
- Design to the workload, not the hype. Throughput, latency, context length, and quality targets dictate hardware.
- Treat the runtime as product. Batching, caching, quantization, and scheduling can halve costs before you change chips.
- Don’t worship SOTA. Right-sized models with strong retrieval often beat bigger models on cost and UX.
- Hedge your hardware. Keep portability: standardized runtimes, interchangeable backends, and transparent benchmarking.
- Measure cost-per-token and cost-per-watt weekly. What you track improves.
Buildloop reflection
“Great AI products don’t chase power — they budget it.”
Sources
- Medium — ASIC Inference vs. Non-Inference AI Chips | by Danny H Lee
- DCNN Magazine — Study finds consumer GPUs can cut AI inference costs
- Fast Company — Nvidia’s rivals are focusing on building AI inference chips. …
- Metamirror — Inference is the real AI race – Steve Jones
- Seeking Alpha — Cerebras launches Inference, which runs 20 times faster …
- YouTube — Nvidia’s Dilemma: AI Learning vs Inference | All-In Podcast
- LinkedIn — InferX: The future of GPU inference is runtime, not layers.
- Substack — Why Inference Will Get Dirt Cheap Fast – by Mike Veerman
- YouTube — Why AI Engineers Need to Understand GPU Hardware (with Chris Fregly)